

Post Summary
What Is Reactive Maintenance?
Reactive maintenance is repair work done after an asset fails or stops working as it should, instead of on a schedule. The work order starts when someone notices something is broken, not when a calendar or a sensor says it is time. It covers everything from swapping a dead light bulb to restoring a walk-in cooler that quit overnight. It is the cheapest strategy up front and the most expensive one when it lands on a critical asset.
The U.S. Department of Energy's O&M Best Practices program, run by Pacific Northwest National Laboratory (PNNL), calls reactive maintenance the "run it until it breaks" approach. PNNL puts the typical facility at more than 55% reactive work, while top programs run under 10% (PNNL, Advanced Maintenance Approach: Reliability-Centered Maintenance). Most operators already do a lot of reactive work, whether they planned to or not.
Each issue should trigger a work order for an in-house technician or an outside vendor. Log the details that matter on every ticket: asset, location, symptom, photo and who reported it. That record lets you confirm the fix held and count what it cost. To get ready for equipment outages, managers assess their asset inventory, gauge priority and create reactive maintenance plans with the critical steps that cut equipment downtime.
For a visual overview, watch the reactive maintenance video walkthrough. For the full ticket lifecycle, see the guide to digital work order management.
Why Reactive Maintenance Matters
Reactive maintenance matters because it decides how much of your repair budget is spent on your terms and how much is spent in a panic. In a 40-store chain, "reactive" is rarely a strategy someone picked. It is the default when a shift lead finds the failure and phones it in. The cost is not just the repair. It is the hours between "it broke" and "the right tech knows."
PNNL lists two benefits of a reactive approach: low cost and less staff. It also lists the risks (PNNL, Maintenance Approaches):
- Higher cost from unplanned equipment downtime
- Higher labor cost, especially when overtime is needed
- The cost of repairing or replacing the equipment
- Possible secondary damage to other equipment or processes
- Inefficient use of staff time
Research outside of stores points the same way. NIST surveyed U.S. manufacturers. The half that relied least on reactive maintenance had 52.7% less unplanned downtime and 78.5% fewer defects than the reactive-heavy half (NIST, Maintenance Costs and Advanced Maintenance Techniques in Manufacturing Machinery). That is factory data, so read it as direction, not a store forecast. At the largest scale, Siemens estimates the world's 500 biggest companies lose almost $1.4 trillion a year to unplanned downtime, about 11% of revenue (Siemens, The True Cost of Downtime 2024). A multi-unit operator feels the same math one store at a time: a dead walk-in, a dark pump, a guest room you can't sell.
Advantages and Disadvantages of Reactive Maintenance
Reactive maintenance has real advantages for the right assets and real disadvantages for the wrong ones. The table below sums up what PNNL, IBM and Fiix describe, in store-level terms.
| Advantages | Disadvantages |
|---|---|
| No upfront planning or PM labor | Unplanned downtime during service hours |
| Lower short-term spend | Emergency and overtime labor rates |
| Fewer staff needed day to day | Secondary damage, such as a failed compressor taking the product with it |
| Fine for cheap, redundant, non-critical assets | Unpredictable budgets and shorter asset life |
| No scheduled equipment stoppages | Safety exposure when failures hit alarms, elevators or gas lines |
The takeaway: use reactive maintenance on purpose for low-impact equipment. Keep it off anything tied to safety, food safety or revenue.
Recommended resources:


Priced on per user or per location basis
Available on iOS, Android and Web


What is Reactive Repair?
Reactive repair is the work done to restore an asset after it has failed or stopped performing, triggered by the failure itself rather than a schedule. It happens after a machine fails or a system crashes, with no planned step taken beforehand to prevent the problem. Reactive repair is the opposite of preventive maintenance, which uses scheduled daily, weekly or monthly tasks to stop problems before they start.
The terms get mixed up, and searchers ask about it often. Some sources treat reactive and corrective maintenance as the same thing. PNNL writes "Reactive maintenance (also called corrective maintenance)" (PNNL). Others split them. Fiix describes corrective maintenance as repair done "after a defect is detected" that "can be planned once the issue appears but before full failure" (Fiix).
The cleanest way to think about it for store teams:
- Reactive repair is the event. Something failed or started failing.
- Corrective maintenance is the work that restores it. That work can be urgent (fix it tonight) or scheduled (fix it Tuesday).
This split matters on the ticket. A cooler that is warm right now and a cooler door that closes a little slow are both reactive. Only one of them needs a technician at midnight.
Types of Reactive Repair(s)
Reactive repairs fall into five types based on the nature and urgency of the repair:
- Emergency repairs: Critical repairs that need attention right away to prevent a safety hazard or major damage, or to restore an essential service. Examples include a gas leak, an electrical outage or a burst pipe.
- Corrective repairs: Fixes for problems spotted during normal operations or inspections. They are less critical than emergencies but still needed to restore full function, such as a dish machine that runs but won't hit temperature.
- Breakdown maintenance: Work to bring a stopped asset back into service after it fails completely, like a broken conveyor belt in a distribution center or an ice machine that won't run.
- Failure maintenance: The asset runs until it stops, and only then is it repaired or replaced. This fits items that are cheap or have a predictable lifespan.
- Postponed maintenance: Repairs delayed because of budget limits or higher-priority work. Left unchecked, it builds a maintenance backlog.
Each type carries a different cost, downtime and operational impact. The right response depends on how critical the equipment is, the resources on hand and the context of the failure.
Safety First: Lockout/Tagout on Rushed Repairs
Any reactive repair that involves opening equipment that could start up or release stored energy falls under OSHA's lockout/tagout standard. The standard "covers the servicing and maintenance of machines and equipment in which the unexpected energization or start up of the machines or equipment, or release of stored energy could cause injury to employees" (OSHA 29 CFR 1910.147).
OSHA's definition of servicing explicitly includes "lubrication, cleaning or unjamming of machines or equipment." That covers a jammed slicer, a mixer that stalls mid-batch or a cardboard baler in the back room. Rushed emergency repairs are where lockout/tagout steps get skipped. A shift lead trying to clear a jam before the lunch rush is exactly the person who needs the procedure. Build the safety step into the reactive SOP, not into a binder nobody opens.
Types Of Reactive Maintenance
The main types of reactive maintenance are emergency, corrective, breakdown, run-to-failure and deferred maintenance. They differ by what triggers them, how fast they need a response and whether the choice was planned. Because reactive maintenance covers such a wide range of work, managers break it into these categories to set the right priority on every ticket.
The table below consolidates the types named by Fiix, ServiceChannel and IBM, with multi-unit examples.
| Type | Trigger | Urgency | Typical multi-unit example |
|---|---|---|---|
| Emergency | Failure threatens safety, food safety or the ability to trade | Immediate, 24/7 | Walk-in cooler down at close. Fire alarm panel fault. Gas leak |
| Corrective | Defect found during use or inspection while the asset still works | Scheduled within a set response window | Cooler door gasket torn. Dispenser screen flickering |
| Breakdown | Asset stops completely | Depends on how critical the asset is | Ice machine dead. Dish machine won't heat |
| Run-to-failure (planned) | Deliberate choice to replace on failure | Low | Back-of-house bulbs. Spare vacuum. Breakroom microwave |
| Deferred | Known issue postponed for budget or labor reasons | Logged and queued | Ceiling stain. Worn carpet in a hotel corridor |

Emergency Maintenance
Emergency maintenance is repair work that must happen immediately to protect the safety of guests and employees, or to keep critical operations running. When an asset fails, the first question a manager should ask is: "Is this an emergency?" Many assets can handle a partial outage or malfunction and still operate well enough to keep the business open. Others need attention right now because of the operational or safety risk the failure creates. Emergency maintenance often costs more when key parts or qualified labor are scarce.
An example of emergency maintenance that puts safety at risk is a malfunctioning alarm system. An example that puts operations at risk is a broken oven at a bakery, because the baker can't produce without it. A broken roller coaster at an amusement park or a stalled ski lift at a resort carries both kinds of risk. Other common emergencies:
- Burst water pipes: fast repair to stop water damage and restore supply
- Electrical outages: restore power and remove shock or fire hazards
- HVAC breakdown in extreme weather: protect the safety and comfort of guests and staff
- Elevator malfunctions: urgent response, especially with passengers trapped inside
- Severe roof leaks: stop structural damage and protect the interior
For restaurants, some emergencies also start a regulatory clock. The FDA Food Code's emergency provision (8-404.11), as adopted in Minnesota, requires an operator to "immediately discontinue operations and notify the regulatory authority if an imminent health hazard may exist because of an emergency such as a fire, flood, extended interruption of electrical or water service, sewage backup..." (Minnesota Rules 4626.1795). A burst pipe or failed water heater can be an emergency work order and a possible closure at the same time. Adoption varies by state, so check your jurisdiction against the FDA Food Code 2022. For the escalation path once an emergency ticket is open, see emergency work order escalation.
Corrective Maintenance
Corrective maintenance covers problems that don't create an immediate safety or operational risk. These issues matter, but the business can keep operating while they wait. The broken part may not be essential to the equipment as a whole, or the asset itself may not be essential to daily operations. Managers have time to compare part prices, collect labor quotes and schedule the work. In some cases they choose to hold the task to protect budget or labor for higher-priority work.
Examples include a broken vending machine at a hotel or light rust on school playground equipment. Corrective work deserves the same discipline as emergencies. If it is not tracked, small issues stack up and turn into an emergency. Strong corrective action apps and a clear corrective maintenance work order process keep that from happening.
In food service, "only corrective" has a limit. Food Code 4-501.11 (good repair and proper adjustment), as adopted in Washington, requires that "equipment components such as doors, seals, hinges, fasteners, and kick plates must be kept intact, tight, and adjusted in accordance with the manufacturer's specifications" (WAC 246-215-04500). A torn walk-in gasket is a corrective ticket until the health inspector writes it up.
Run to Failure Maintenance
Run-to-failure maintenance is a deliberate plan to let an asset operate until it breaks, then repair or replace it. It fits assets that aren't valuable enough to justify ongoing preventive maintenance and monitoring. It also fits assets that are plentiful enough for backups to cover the gap, or that aren't central to daily operations. Run-to-failure should never be used on critical operating equipment or safety equipment.
Examples of run-to-failure maintenance include basic electrical items such as light bulbs, televisions and telephones. These can be replaced quickly and don't need ongoing status checks to protect uptime. The key word is deliberate. A run-to-failure list is a decision written down in advance, so a store team knows a dead breakroom microwave is a "replace when convenient" item, not a 2am call. For a deeper look at choosing these assets, read the run-to-failure maintenance guide.
Deferred Maintenance
Deferred maintenance is a known repair that gets postponed, usually for budget or labor reasons. Fiix calls this "deferred corrective" maintenance. It is reactive because the defect already exists. It is different from run-to-failure because nobody decided the asset should fail. The work was simply pushed back.
Deferral is sometimes the right call. A ceiling stain in a back office can wait for the next budget cycle. The risk is that deferred tickets pile up quietly until a group of small problems becomes one large outage. Every deferred item should stay logged, dated and reviewed, with a clear trigger that moves it back to the active queue. The deferred maintenance definition covers the term, and the guide to maintenance backlog management shows how to keep the queue from growing out of control across locations.
Where Xenia Fits: Getting the Failure Reported Faster
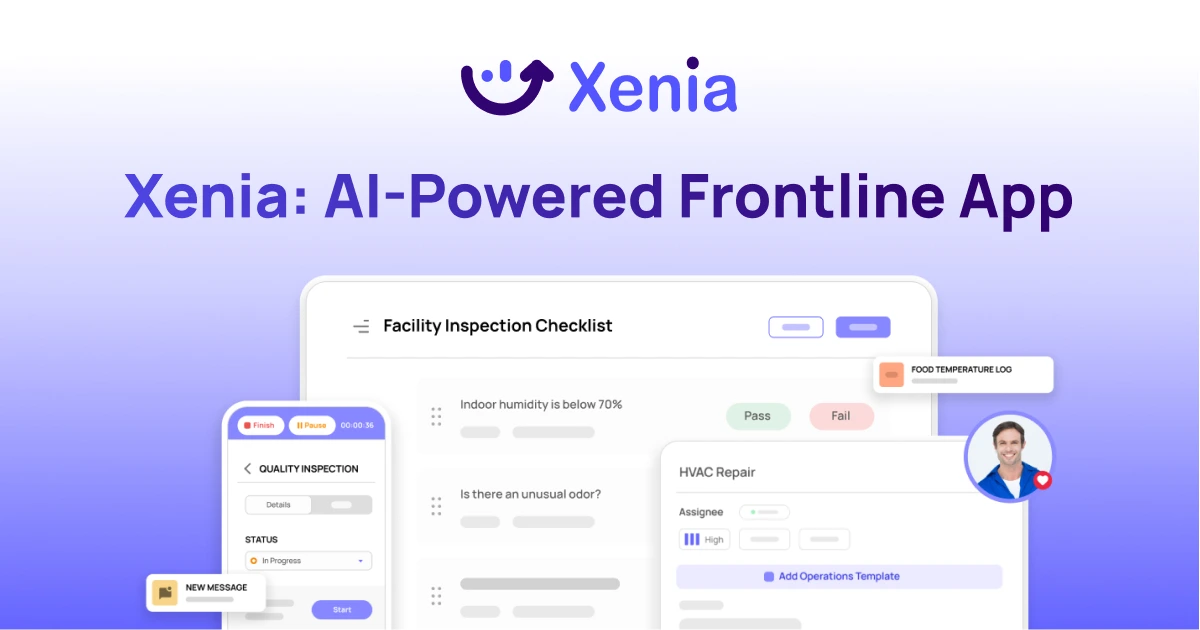
In most reactive repairs, the slowest step is the report, not the repair. The cashier or line cook who finds the problem has to find a manager. The manager has to call someone. Someone has to open a ticket. With Xenia, store staff or third-party vendors submit work requests via QR code without logging in. The form auto-populates the asset, location and category, and the person adds a photo. A manager approves the request and routes it by priority, location and team. See how QR-code work requests with no login work, or browse Xenia work order software.
To be fair about scope: Xenia handles frontline work order submission and routing. If you need deep parts inventory, depreciation tracking or vendor invoicing, a full CMMS still leads. The side-by-side of Xenia vs. ServiceChannel lays out where each tool fits.
Examples Of Reactive Maintenance
Reactive maintenance looks different in every vertical, but the pattern is the same: some failures are emergencies, some can wait and some assets should run to failure. The examples below show how hotels, senior living communities, country clubs, schools, restaurants and convenience stores sort that work. Each one names the assets that need an emergency plan and the ones that can be handled case by case.
Use these as a starting point for your own asset list. The goal is not to copy another operator's priorities. It is to decide yours before the failure happens, so the person who finds the problem knows what to do next.
Hotel Industry Example
The hotel industry depends on many types of reactive maintenance to stay profitable. Every property has equipment that directly affects guest experience, so failures there count as emergency reactive maintenance. These range from large systems such as HVAC and boiler room equipment to smaller but high-impact items like a broken elevator or a room key reader. For these assets, managers need preventive maintenance schedules to limit breakdowns and reactive maintenance SOPs to cut downtime when something does break.
ServiceChannel's hotel scenario shows how one HVAC failure on a hot day cascades: guest complaints, refunds, overtime, emergency service fees, rush-ordered parts and bad reviews (ServiceChannel). The repair invoice is only one line of that bill.
Hotels also have assets that fit a run-to-failure model. These include vending machines, laundry and housekeeping carts, luggage carts and more. Because replacement costs are low and the business impact is limited, they can be handled case by case.
Senior Living Industry Example
Senior living communities rely heavily on reactive maintenance because their facilities are large and spread out. That makes it hard to predict when equipment will fail or need service. Assets are scattered across the community, which means less oversight and very local impacts. Detailed reactive maintenance plans need to cover the location and impact of each asset that goes down.
Emergency reactive maintenance in senior living includes broken accessibility equipment for residents and failed electrical or HVAC systems. Any of these raises the risk of an accident for residents and needs a matching level of urgency. Communities also have assets where time matters less, such as a broken golf cart when the property has several. In those cases, the down asset doesn't raise operational or safety risk, and the repair can be scheduled.
Country Club Industry Example
The country club industry is one of the clearest examples of reactive maintenance in practice. Clubs manage golf courses, which are large, complex investments. Keeping them in good condition is central to the member and guest experience.
Golf course upkeep blends preventive maintenance with reactive work. Watering, fertilizing, mowing, trimming and weeding should all run on a schedule. Reactive work orders still come up. A good example is filling divots left by players in fairways and tee boxes. These start as corrective maintenance, but if they pile up they quickly become an emergency for the playing experience. Carts, irrigation heads and clubhouse equipment follow the same split: the course can't open without some of them, and others can wait a day.
School / University Industry Example
Reactive maintenance is an essential part of running any school or university. Students, faculty and staff put heavy wear on buildings and equipment, and safety comes first.
In elementary schools, even basic maintenance can be emergency maintenance. Any asset used by children, or relied on for their care, needs extra attention and a fast fix when it fails. Other items such as chalkboards, minor toilet issues or fading playground paint can be handled on a slower schedule.
Universities face a different problem. Maintenance staff don't always have regular access to dorm rooms, so issues often go unreported until an asset is completely broken or the semester ends. Furniture, lighting, carpet and wall damage fall into this category. Managers should expect many work orders to arrive at once, which can turn small issues into larger outages. A plan for maintenance backlog management keeps end-of-term surges from swamping the team.
Restaurant / QSR Industry Example
In restaurants, the classic reactive emergency is a walk-in compressor that fails after close. Nobody notices until the morning temp check. That is emergency reactive maintenance with a food-safety clock attached. Product must be evaluated, and possibly discarded, before service starts. The repair ticket and the walk-in cooler temperature log become part of the same record.
Corrective items in a kitchen include a torn cooler gasket, a fryer thermostat that drifts or a hood light that burns out. Run-to-failure assets include smallwares and back-office printers. The difference between a good and bad morning is often how fast the opener can report the problem and reach the right tech. In practice, a kitchen manager scans the QR code on a broken fryer and the work request routes to the maintenance team with the photo attached. For tracking repeat failures across locations, see restaurant equipment maintenance software.
Convenience Store / Fuel Industry Example
In a convenience store, a dispenser goes down at 11pm and the closing attendant is the only person on site. Whether that is an emergency depends on the failure. A leaking pump is a safety emergency. A pump that is simply offline is a revenue problem that can often wait for the morning tech.
Cooler doors that won't seal are corrective work, and they matter because product temperature is on the line. Restroom fixtures and parking lot lighting often run to failure, though lighting can become a safety issue at night. The attendant needs a reporting path that works without a manager on site. A pump attendant scans the QR code on a faulty pump, and the request routes to the area tech by region and notifies the DM. The guide to c-store work order management covers the full forecourt-to-backroom workflow.
How To Minimize Impact Of Reactive Maintenance
You minimize the impact of reactive maintenance by deciding, before anything breaks, which assets matter most, how they fail and what the response will be. You can't stop every asset from breaking. You can shrink the damage when it happens. The process has seven steps:
- List every asset and score how critical it is.
- Learn what a breakdown looks like for each one.
- Estimate how likely each breakdown is.
- Price the reactive fix and line up vendors in advance.
- Price the preventive alternative.
- Put the preventive budget on high-risk, high-impact assets.
- Write reactive procedures and priority tiers for everything else.
Understanding Your Equipment Scope and Needs
The first step is knowing exactly which equipment and physical assets you have to maintain. That includes which assets are in use and whether they perform as expected. To begin, list every asset in the business, big and small, in an asset register.
Next, score each asset so you can rank the work. ServiceChannel recommends "an asset criticality matrix ranking equipment by safety, operations, and spend" (ServiceChannel). A simple version scores each asset 1 to 3 on five factors and adds them up:
| Factor | Score 1 (low) | Score 3 (high) |
|---|---|---|
| Safety impact | No injury risk if it fails | Failure can hurt staff or guests |
| Food safety or compliance impact | No regulatory exposure | Failure can trigger a violation or closure |
| Revenue impact | Business runs normally | Location can't trade or sell a core item |
| Replacement cost | Cheap, off the shelf | Expensive or long lead time |
| Redundancy | Several backups on site | Single unit, no backup |
Also note frequency of use and whether repairs are done in-house or by an outside vendor. High totals get preventive plans and emergency SOPs. Low totals are run-to-failure candidates.
Knowing What a Breakdown Looks Like
The next step is understanding how each asset can break down. Spend the most time on assets that are expensive and that have a big effect on operations and safety. Use past work orders, technician knowledge and manufacturer guidance to find assets that fail often or fail in many different ways. A structured method like failure modes and effects analysis (FMEA) helps here, because it lists each way an asset can fail and what happens next.
Also note assets with only a few ways to break down. These are the easiest to write reactive SOPs for, because the response is predictable. For store teams, the useful output is a short "what you'll see" list per asset. For example: the walk-in reads warm, the compressor is silent, the fan is iced over. That list tells the person on shift what to report.
Understanding the likelihood of that breakdown occurring
Once you know your assets and the ways they can fail, estimate how likely each failure is. Asset age and usage have a big effect. A five-year-old ice machine running two shifts a day is far more likely to fail than a new unit in a slow location.
Past work orders are the best source here. If the same dish machine at three stores has needed a technician every quarter, that is not bad luck. It is a pattern. Combine likelihood with the criticality score from step one. An asset that is both likely to fail and critical is your top priority for preventive work and for a written emergency response. An asset that is unlikely to fail and low impact can stay on the run-to-failure list with no further planning.
Understanding the cost of solving a breakdown through reactive maintenance
Once you know which assets are likely to go down, research what each failure would cost. This lets you forecast reactive maintenance costs instead of discovering them on the invoice. Include the repair, the parts, emergency or overtime rates, lost sales and any product you would have to throw away.
This step is also when you front-load the contractor research. Pick approved vendors and set spending limits in advance, so fast action doesn't mean overpaying or hiring an unqualified technician. A store should never be shopping for a refrigeration tech at 11pm. Write down who to call for each asset type, the after-hours number and the dollar amount the store can approve without calling the DM.
Understanding the cost of preventive maintenance of the asset
Next, price a preventive maintenance plan for each important asset and estimate its effect on failure likelihood and repair cost. Many assets perform much better with regular care. When you compare capital spending through both a reactive and a preventive lens, you can make confident decisions about your bottom line.
There is solid evidence that the trade pays off. DOE and PNNL estimate preventive maintenance saves 12 to 18 percent compared with a reactive program, and predictive maintenance saves a further 8 to 12 percent over preventive (PNNL). Be careful with the widely repeated claim that reactive work costs "3 to 5 times more." ReliaMag traced it back to the DOE guide it is usually credited to and reports "The phrase isn't there" (ReliaMag). Use your own repair history instead.
Prioritizing the budget to focus preventive maintenance on high risk, high impact assets
When the preventive maintenance budget is limited, put it where risk and impact are both high. Those are the assets with the highest criticality scores and the highest likelihood of failure. In a restaurant group, that usually means walk-ins, hoods, fryers and HVAC. In a convenience store, it means dispensers, coolers and the POS. In a hotel, it means HVAC, boilers and elevators.
Everything else gets a written decision: either a lighter preventive check or a deliberate run-to-failure plan. The point is that nothing ends up reactive by accident. Review the split once a year, or sooner if a location keeps generating the same emergency ticket. A repeat failure is the clearest signal that an asset belongs on the preventive list.
Creating reactive maintenance procedures for all assets to be implemented in a time of breakdown
With a ranked asset list in hand, write a reactive procedure for each asset or asset group. Store these documents where frontline teams can reach them on shift, and update them often so they stay accurate and capture what you learned from past failures.
Pair the procedures with priority tiers so every ticket gets the right response time. Here is an example set of tiers an operator might use. Treat it as a template to adjust, not an industry standard:
| Tier | Meaning | Example response target |
|---|---|---|
| P1 Emergency | Safety, food safety or ability to trade at risk | Respond in under 1 hour, 24/7 |
| P2 Urgent | Major function impaired, workaround exists | Same day |
| P3 Standard | Defect present, business unaffected | Within 3 to 5 days |
| P4 Planned or deferred | Known issue, scheduled or postponed | Next planned visit |
For more on setting tiers and routing rules, read the guide to work order prioritization.
Using a RACI Chart to Manage Reactive Maintenance
A RACI chart assigns who is Responsible, Accountable, Consulted and Informed for each step of a reactive repair, so nobody wonders who calls the vendor. When a breakdown happens, everyone involved needs to know their role in getting the asset back up and running. RACI charts give each person clear action guidance and bring several perspectives to every issue.
The role definitions from IT@Cornell's RACI guidance are a good standard:
- Responsible: "A person or team responsible for correct execution of the task"
- Accountable: "Only one per task/deliverable/decision. A person who has ownership of quality and the end result"
- Consulted: "People whose opinions are sought"
- Informed: "People who are kept up-to-date on progress"
The key rule: "You can only have one A for an item in the RACI." If two people own the outcome, nobody does.

RACI charts work for any project, but they help most when the work crosses departments or teams. That makes them especially useful for coordinating outside contractors and confirming internally that the work met the standard. Here is a worked example for one reactive event, a walk-in cooler failure at a multi-unit restaurant:
| Step | Shift lead | Store GM | Facilities manager | Refrigeration vendor | District manager |
|---|---|---|---|---|---|
| Report failure with photo and temp reading | R | A | I |  |  |
| Protect product (move, evaluate, log) | R | A |  |  | I |
| Classify priority and dispatch |  | C | A and R | I | I |
| Diagnose and repair |  | I | A | R |  |
| Verify temps back in range, close ticket | R | A | C | C | I |
| Log cost and root cause |  | C | A and R | C | I |
The same chart adapts to other verticals. In a hotel, swap in the front desk, chief engineer and general manager. In a c-store, swap in the clerk, store manager, area tech and fuel equipment vendor. Keep one Accountable per row and post the chart where the shift team can see it.
How To Create A Reactive Maintenance SOP
A reactive maintenance SOP is a written procedure that tells store teams exactly what to do, who to call and what proof to capture when a specific asset fails. This section walks through a five-step process for building and managing standard operating procedures (SOPs), followed by the core workflow every reactive SOP should follow.

Step 1: Develop a list of processes you believe need SOP creation
Start by listing the processes that need an SOP. This keeps the team focused on the right procedures and avoids wasting time on ones that won't get used. Focus on assets with a high impact and a predictable way of breaking down. Those SOPs are the most likely to be relevant when the failure actually happens.
Step 2: Determine "Proof of Work" content for your SOP
Next, decide what each SOP needs to contain. Does it need photos or graphics? Step-by-step instructions? Different versions for different roles or locations? Decide what proof closes the job. A required photo of the finished repair, a test reading and the technician's name are common choices. These answers define what each record must include.
Step 3: Plan the process for managing and measuring SOPs
Plan how SOPs will be developed and managed. Define where they are stored, who can access them, when they get updated and what happens if an update is missed. Name who owns each document and how changes get approved. Also review each SOP for measurability. A manager should be able to measure success and speed from every SOP, so it can be improved over time.
Step 4: Review, publish and deploy your SOP
Write the SOP in clear, short language. Edit it to make sure it includes everything a store team needs at 2am with no manager on site. Publish it where frontline staff can find it on shift, then confirm the team has read it. Review it often to keep it current.
Step 5: Maintain and optimize your SOP over time
Once an SOP is live, maintain it. Update it every time something changes in your facility, such as adding new equipment or modifying an existing unit. Use each update to check for other needed changes. When the process changes or new procedures are added, update the SOP and make sure everyone knows.
The Core Reactive Maintenance Workflow
Every reactive SOP should follow the same core workflow, from the moment a failure is found to the moment the asset is back in service:
- Failure identification: A staff member, operator or monitoring system spots the failure.
- Issue reporting: The issue goes to the maintenance team through a defined channel, not a hallway conversation.
- Assessment and prioritization: The team judges severity and impact and assigns a priority tier.
- Dispatch: The right in-house tech or approved vendor is sent to the location.
- Diagnosis: The technician finds the root cause of the failure.
- Repair or replacement: The technician fixes the issue or replaces faulty parts.
- Testing and validation: The equipment is tested to confirm it works correctly and safely.
- Documentation and feedback: The failure, repair, parts and any notes for future prevention are recorded.
- Resume operations: The asset goes back into service once it is confirmed working.
In store terms, the flow reads like this: report (QR scan and photo), triage (priority tier, safety check, lockout/tagout if needed), route (in-house tech or approved vendor), repair, verify (test, photo, temp reading), close (cost, parts, root cause) and review (repeat failures feed the PM list). For the ticket-level version of this workflow, see reactive maintenance work orders.
What Every Reactive SOP Must Specify
A reactive SOP is only useful if it answers the questions a shift lead will have in the moment. Every SOP should spell out:
- Who can declare an emergency. Name the role, not a person who might be off shift.
- The after-hours contact chain. Who to call first, second and third, with numbers.
- The spending limit a store can approve without a call. This keeps small repairs from waiting on a DM.
- The safety step. OSHA requires that "Procedures shall be developed, documented and utilized for the control of potentially hazardous energy" (29 CFR 1910.147(c)(4)(i)). If the repair touches energized equipment, lockout/tagout belongs in the SOP.
- The food-safety step for refrigeration failures. Who checks product, how it is evaluated and where the decision is logged.
- The closure evidence required. Photo, test result, technician name and cost.
How To Track Reactive Maintenance Costs
To track reactive maintenance costs, tag every work order by type, log labor, parts and vendor costs on the ticket and review the totals by asset and location. Most organizations don't have a dedicated process for this, which makes reactive spend hard to see. It blends into general repairs and nobody can say how much of the budget went to surprises.
Start with tagging. Label each work order as emergency, corrective, preventive or routine. That one field separates reactive spend from planned spend and makes every other metric possible. The good news is that there are several practical ways to build the rest of the picture.
Use Digital Checklists & SOPs
Digital checklists are a practical way to track equipment condition. They help teams spot problems before they turn into failures, and they put repair instructions in front of the person doing the work.
Digital checklists also show how often specific repairs happen, which points to problem areas in your facility or across locations. When repair costs are logged against each asset's SOP and work order, managers can total reactive maintenance costs by asset over time. That turns a vague sense that "the fryers are always breaking" into a number you can take to the budget meeting.
Xenia work orders capture location, asset, urgency, photos and assignee. They track labor time and costs per request and keep a full work history you can filter by location, asset, vendor and date. You can export cost and resolution-time reports (Xenia work orders). That gives frontline cost visibility across stores. It is not a replacement for CMMS-grade parts or invoice accounting.
Use Cost Schedule
If your facility has many components that need separate maintenance, a cost schedule helps make sure each one is covered. The schedule lists the parts needed for each piece of equipment and its standard maintenance needs.
It also includes an estimate of what a failure or unexpected breakdown would cost. That way you know how much is spent each year on repairs and maintenance inspections. Compare the schedule against actual work orders every quarter. When actual reactive spend on an asset runs well above its scheduled cost, that asset is a candidate for preventive work. Free tools like the maintenance work order log and a work order form template make a good starting point if you are still on paper.
Reactive Maintenance Metrics to Track
Once tickets are tagged and costed, a few metrics tell you whether reactive work is under control:
| Metric | What it tells you |
|---|---|
| Reactive share of work orders or spend | How much of the budget is unplanned. See planned maintenance percentage (PMP) |
| Mean time to repair | How fast failures get fixed. See MTTR |
| Mean time between failures | Which assets fail repeatedly. See MTBF |
| Cost per asset and per location | Which stores or units drain repair spend |
| Repeat work orders on the same asset within 30 to 90 days | Fixes that didn't hold, a signal for root cause analysis |
| Time from report to assignment | How much friction sits in the reporting step |
Benchmark honestly. PNNL's figures (more than 55% reactive on average, under 10% in top programs) are the citable reference (PNNL). The often-quoted planned-maintenance targets from SMRP aren't publicly verifiable, because ReliaMag notes they live in SMRP's copyrighted Best Practices document (ReliaMag KPI reference). Your best benchmark is your own trailing 12 months. For a deeper list, read maintenance KPIs and work order metrics.
Other Maintenance Strategies To Consider
The opposite of reactive maintenance is preventive maintenance, which uses scheduled inspections and tasks to stop failures before they happen. Preventive is not the only option. Most operators run a mix of reactive, preventive, predictive and condition-based work, matched to how critical each asset is. The goal is not to eliminate reactive maintenance. It is to make sure reactive work only happens where you chose it.
|  | Reactive | Preventive | Predictive | Reliability-centered (RCM) |
|---|---|---|---|---|
| Trigger | Failure | Calendar or usage | Measured condition | Asset criticality analysis |
| Upfront cost | Lowest | Moderate | Highest (sensors, software) | High (analysis) |
| Savings vs. prior tier (DOE and PNNL estimate) | Baseline | 12 to 18% vs. reactive | 8 to 12% vs. preventive | Not separately estimated |
| Best for | Cheap, redundant, non-critical assets | Walk-ins, HVAC, boilers, hoods, dispensers | High-value rotating equipment | Portfolios with mixed criticality |
Source for savings estimates: PNNL.
Preventive Maintenance
Preventive maintenance is regular, scheduled checkups and part replacements done before equipment fails. Preventive maintenance avoids major failures by keeping equipment in good working order. It is the most common step up from a reactive program, and it is where DOE and PNNL estimate the 12 to 18 percent savings.
Preventive maintenance is not only about equipment. It also includes process improvements and employee training. It usually runs on fixed cadences such as weekly, monthly, quarterly and annually. Filter changes, coil cleaning, gasket checks and hood cleaning are typical store-level tasks. The best way to keep track is a central digital calendar, such as the free preventive maintenance calendar. For help setting cadences, read how to build a preventive maintenance schedule.
Predictive Maintenance
Predictive maintenance uses sensor data to predict when equipment will fail and alert staff before the problem causes expensive damage. Instead of servicing on a calendar, the team services when the data shows wear, such as rising vibration, heat or power draw.
This approach requires dedicated software and hardware, so plan for that investment before you start. The payoff can be real. NIST found that manufacturers relying more on predictive than preventive maintenance had 18.5% less unplanned downtime and 87.3% fewer defects (NIST). For most multi-unit operators, predictive work makes sense on a small set of high-value assets first. Compare options in this review of predictive maintenance tools.
Condition-Based Maintenance
Condition-based maintenance (CBM) triggers service when an asset's measured condition crosses a set threshold. It sits between preventive and predictive. Preventive work happens on a schedule whether the asset needs it or not. CBM waits until a reading or an inspection shows that it does.
In a store, CBM can be as simple as a reading on a daily checklist. A cooler that holds temperature gets no ticket. A cooler that starts drifting gets a service call before it fails. The same logic applies to fryer oil quality, water filter pressure or a pump that slows down. CBM needs consistent readings to work, so it pairs best with disciplined daily checks. When the readings are good, CBM catches the slow failures that would otherwise show up as an emergency on a busy night.
Reliability-Centered Maintenance
Reliability-centered maintenance (RCM) analyzes how each asset fails and what that failure costs, then assigns the right strategy to each one. PNNL treats RCM as the advanced approach that mixes all of the others. Under RCM, reactive maintenance is not a failure of planning. It is a deliberate choice for assets where it is the cheapest safe option.
RCM takes more analysis up front, which is why it fits portfolios with a wide mix of equipment. A 50-unit chain doesn't need a formal study to use the idea. The criticality scoring and failure-mode steps earlier in this guide are a lightweight version of the same thinking. Score each asset, decide how it fails, then choose reactive, preventive, condition-based or predictive work for it.
Ongoing Maintenance
Ongoing maintenance is a program of routine inspection rounds and checks done on a fixed interval, every few months or years, instead of waiting for something to break. It is closely related to periodic maintenance. The aim is to catch wear early with a regular walk-through of systems and equipment.
Ongoing maintenance is not automatically cheaper than other strategies. Its value comes from finding small problems while they are still corrective tickets, before they become emergencies. A quarterly roof walk, a semi-annual electrical panel check or a yearly boiler inspection all fit here. Pair these rounds with a clear way to turn each finding into a work order, so the inspection actually leads to a repair.
Wrapping Up
Reactive maintenance is unavoidable, so the goal is to make it deliberate. Every operator will have assets that break between visits. The difference between a costly reactive program and a controlled one comes down to three habits.
- Choose which assets run to failure. Write the list down so store teams know what can wait.
- Shrink the time between failure and report. The faster the right person knows, the shorter the downtime.
- Feed every repeat failure back into the PM plan. A ticket that keeps coming back is telling you where to invest.
Reactive maintenance does not reduce unplanned downtime. Unplanned downtime is what it responds to. What reduces downtime is the work around it: criticality scoring, preventive plans for high-risk assets, clear SOPs, a RACI that names one owner and cost tracking that shows where the money goes. DOE and PNNL estimate that moving work from reactive to preventive saves 12 to 18 percent, so every asset you move off the reactive list is money back in the budget.
The weakest link in most multi-unit programs is still the first one: getting a failure from the person who found it to the person who can fix it. Xenia closes that gap with QR-code work requests that need no login, routing by priority and location, and a full cost and resolution history per asset. Learn how reactive maintenance work orders run end to end, see all work order features. Ready to see it on your own assets? Book a demo of Xenia work orders.
Frequently Asked Questions
Got a question? Find our FAQs here. If your question hasn't been answered here, contact us.
What is reactive maintenance and why is it important in facility management?

What are the different types of reactive maintenance, and how do they differ?
How can managers minimize the impact of reactive maintenance?
What is a RACI chart, and how is it used in managing reactive maintenance?
Why should facilities consider other maintenance strategies alongside reactive maintenance?

A Modern, AI-Powered Platform Built Specifically for Frontline Operations
Xenia brings daily operations, maintenance, audits, and compliance into one mobile-first platform. Frontline teams execute work consistently across locations while leadership gets real-time visibility.
Why Multi-Location Operators Choose Xenia:
🤖 AI-Powered Operations, Create digital checklists instantly or convert paper forms with AI. Verify compliance automatically with photo analysis and get instant answers from your operational data.
✅ Daily Operations & Maintenance, Assign work across hundreds of locations in minutes. Report and route issues instantly. Schedule preventive maintenance to catch problems before downtime.
📊 Real-Time Visibility, Track completion, work orders, and performance across all locations through dashboards. Filter by site or asset to spot trends and take action.
Manage operations, maintenance, and compliance across all your locations from one platform